Fine-Tuning vs. Frozen LLM Embeddings: Choosing a Classifier for Your Task
Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head
Iván Palomares Carrascosa wrote this article, published October 27, 2026, in Language Models.
The central question is practical: when a domain task calls for adapting a large language model, do you need to change the model’s weights, or can you keep its representations fixed and train a smaller classifier on top? That choice affects both compute cost and predictive performance, and the answer depends on the task and the resources available.
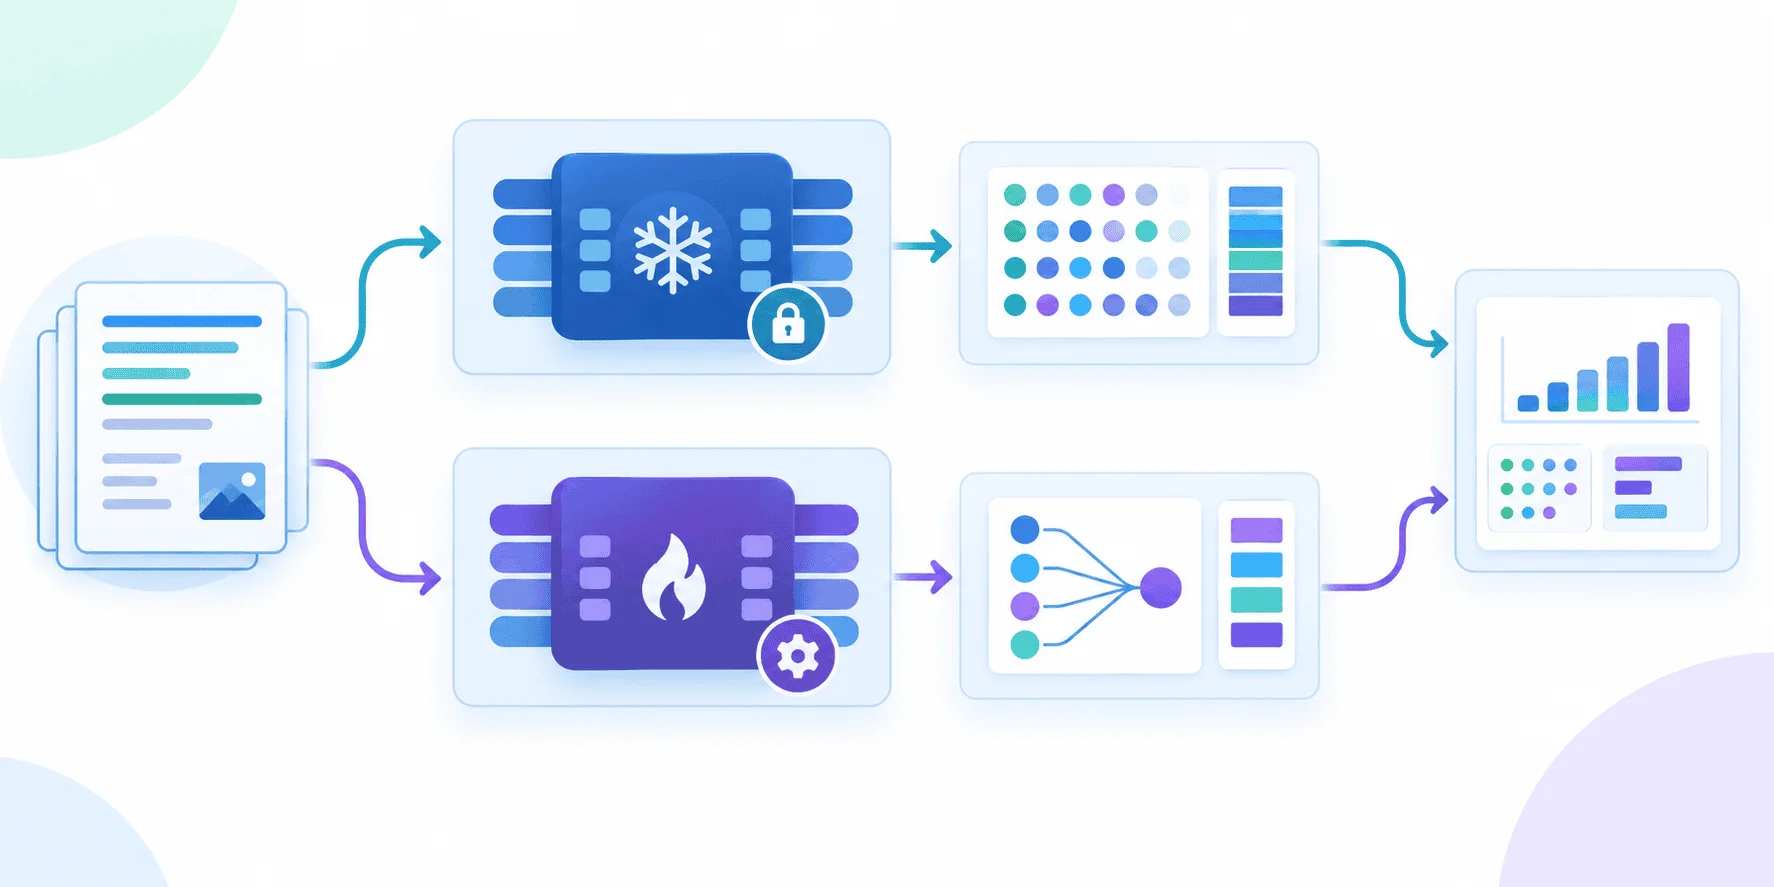
Two ways to adapt a model
Fine-tuning is the familiar route: train a model on domain-specific examples so its weights adjust to the task. LoRA, or Low-Rank Adaptation, makes that process more efficient by updating a smaller set of parameters. The alternative keeps the LLM frozen, extracts embeddings from its text representations, and fits a lightweight scikit-learn classifier to those vectors.
This comparison is useful because fine-tuning isn’t automatically the right answer. Frozen embeddings can make sense when compute or budget is tight; adapting the model may perform better when the existing representations don’t capture what the task needs. The article tests both approaches for classification, looking at training time and accuracy. The numbers will matter, but the setup matters too: this is a small demonstration, not a broad benchmark.
A compact classification experiment
The walkthrough uses the AG News dataset from Hugging Face, which assigns news articles to four categories. It compares LoRA fine-tuning with a scikit-learn classifier trained on frozen embeddings, using QLoRA and the PEFT library alongside Hugging Face tools.
To keep the run short, the code samples 800 shuffled training examples and 200 shuffled test examples, using seed 42. The selected model is Qwen/Qwen2.5-1.5B; the code comments that readers can substitute meta-llama/Meta-Llama-3-8B. That scale makes the experiment approachable, though results from such a small subset won’t settle which strategy wins on larger or more specialized datasets.
If you follow along in Google Colab, the instructions call for a T4 GPU. The install command adds bitsandbytes, peft, accelerate, and evaluate. In another Python environment, you’ll also need scikit-learn, transformers, and datasets. The example imports PyTorch, NumPy, timing utilities, Hugging Face’s dataset loader, and transformer classes for tokenization, sequence classification, and quantization configuration.
Some familiarity with LLMs, fine-tuning, and the Hugging Face transformers library will help. The next setup step loads the model and tokenizer with a classification head configured for the dataset’s four labels.
Preparing the model for four-class classification
The setup keeps the base model small enough to run with 4-bit weights, then attaches a sequence-classification head with four outputs. That’s a practical memory trade-off, though the code alone doesn’t tell us how much accuracy the quantization costs.
For a decoder-only model, the tokenizer’s end-of-sequence token is reused for padding. The model’s padding ID is then set to match. The configuration uses NF4 quantization, bfloat16 computation, and automatic device placement:
print("2. Configuring Tokenizer...")
tokenizer = AutoTokenizer.from_pretrained(MODEL_ID)
tokenizer.pad_token = tokenizer.eos_token  # Needed for decoder-only models

print("3. Loading Base Model in 4-bit...")
bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_compute_dtype=torch.bfloat16,
    bnb_4bit_quant_type="nf4"
)

# Load the model with a classification head
model = AutoModelForSequenceClassification.from_pretrained(
    MODEL_ID,
    num_labels=4,
    quantization_config=bnb_config,
    device_map="auto"
)
model.config.pad_token_id = tokenizer.pad_token_id
Strategy A: Frozen embeddings and a Scikit-learn classifier
The alternative to fine-tuning is to leave the language model’s weights untouched and use it as a feature extractor. Text passes through the frozen model; a separate classifier learns from the resulting vectors. This can make experimentation simpler because the large model doesn’t need to be updated, but the quality of the final classifier still depends on how well those vectors represent the task.
There’s a small but meaningful difference between the description and the implementation here: the prose refers to taking the final token’s embedding, while the function below averages the hidden vectors across all non-padding tokens. It batches inputs in groups of eight by default, truncates sequences at 128 tokens, and returns the pooled vectors as NumPy float32 arrays.
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import accuracy_score

def extract_embeddings(texts, batch_size=8):
    model.eval()
    embeddings = []

    for i in range(0, len(texts), batch_size):
        batch = texts[i:i + batch_size]
        inputs = tokenizer(
            batch,
            return_tensors="pt",
            padding=True,
            truncation=True,
            max_length=128
        ).to(model.device)

        with torch.no_grad():
            # Request the model's hidden-state vectors
            outputs = model(**inputs, output_hidden_states=True)
            last_hidden_state = outputs.hidden_states[-1]

            # Average across tokens while excluding padding
            mask = inputs["attention_mask"].unsqueeze(-1).float()
            sum_embeds = torch.sum(last_hidden_state * mask, dim=1)
            mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e-9)

            embeddings.append(mean_pooled.cpu().numpy().astype(np.float32))

    return np.concatenate(embeddings, axis=0)

